AI Visibility Score Reliability and What Makes Them Misleading
AI visibility scores mask fundamental instability in how these systems work.
AI visibility scores have become a standard line item in marketing budgets, and the reliability of those scores is now a business question rather than a technical footnote. An AI visibility score is meant to track how often and how prominently a brand turns up inside AI-generated answers, whether through a direct mention, a citation, or an outright recommendation, treating that frequency as a stand-in for brand presence in the new discovery layer that sits between a customer and a search box.
What AI visibility scores claim to measure
The appeal of these scores is easy to understand once the context is clear. Marketers who have watched click traffic from Google shrink as more answers resolve inside the AI chat window, with no click at all, need a number to bring to the board, and an AI visibility score is built to fill that exact gap. The tools producing these scores, generally sold as AEO or GEO platforms, bundle prompt monitoring, citation tracking, brand mention analysis, and competitive reporting into one dashboard figure.
That's the appeal, and it's also where the trouble starts. These dashboards report figures to one decimal place, the kind of precision usually reserved for measurements with a known margin of error and a repeatable method behind them. The engines generating the underlying answers are probabilistic by design, and the infrastructure used to measure them sits entirely inside each vendor's own closed system. The number on the dashboard looks exact without being verifiable by anyone outside the company that produced it.
How LLM probabilistic outputs destabilize visibility scores
A visibility score reported as a single figure is misleading from the start, because the system producing the underlying answers does not give the same answer twice. Ask the same question of the same AI assistant on two different days and the brands it names, the sources it draws from, and the order in which it presents them can all come back different, simply because that is how these systems generate text.
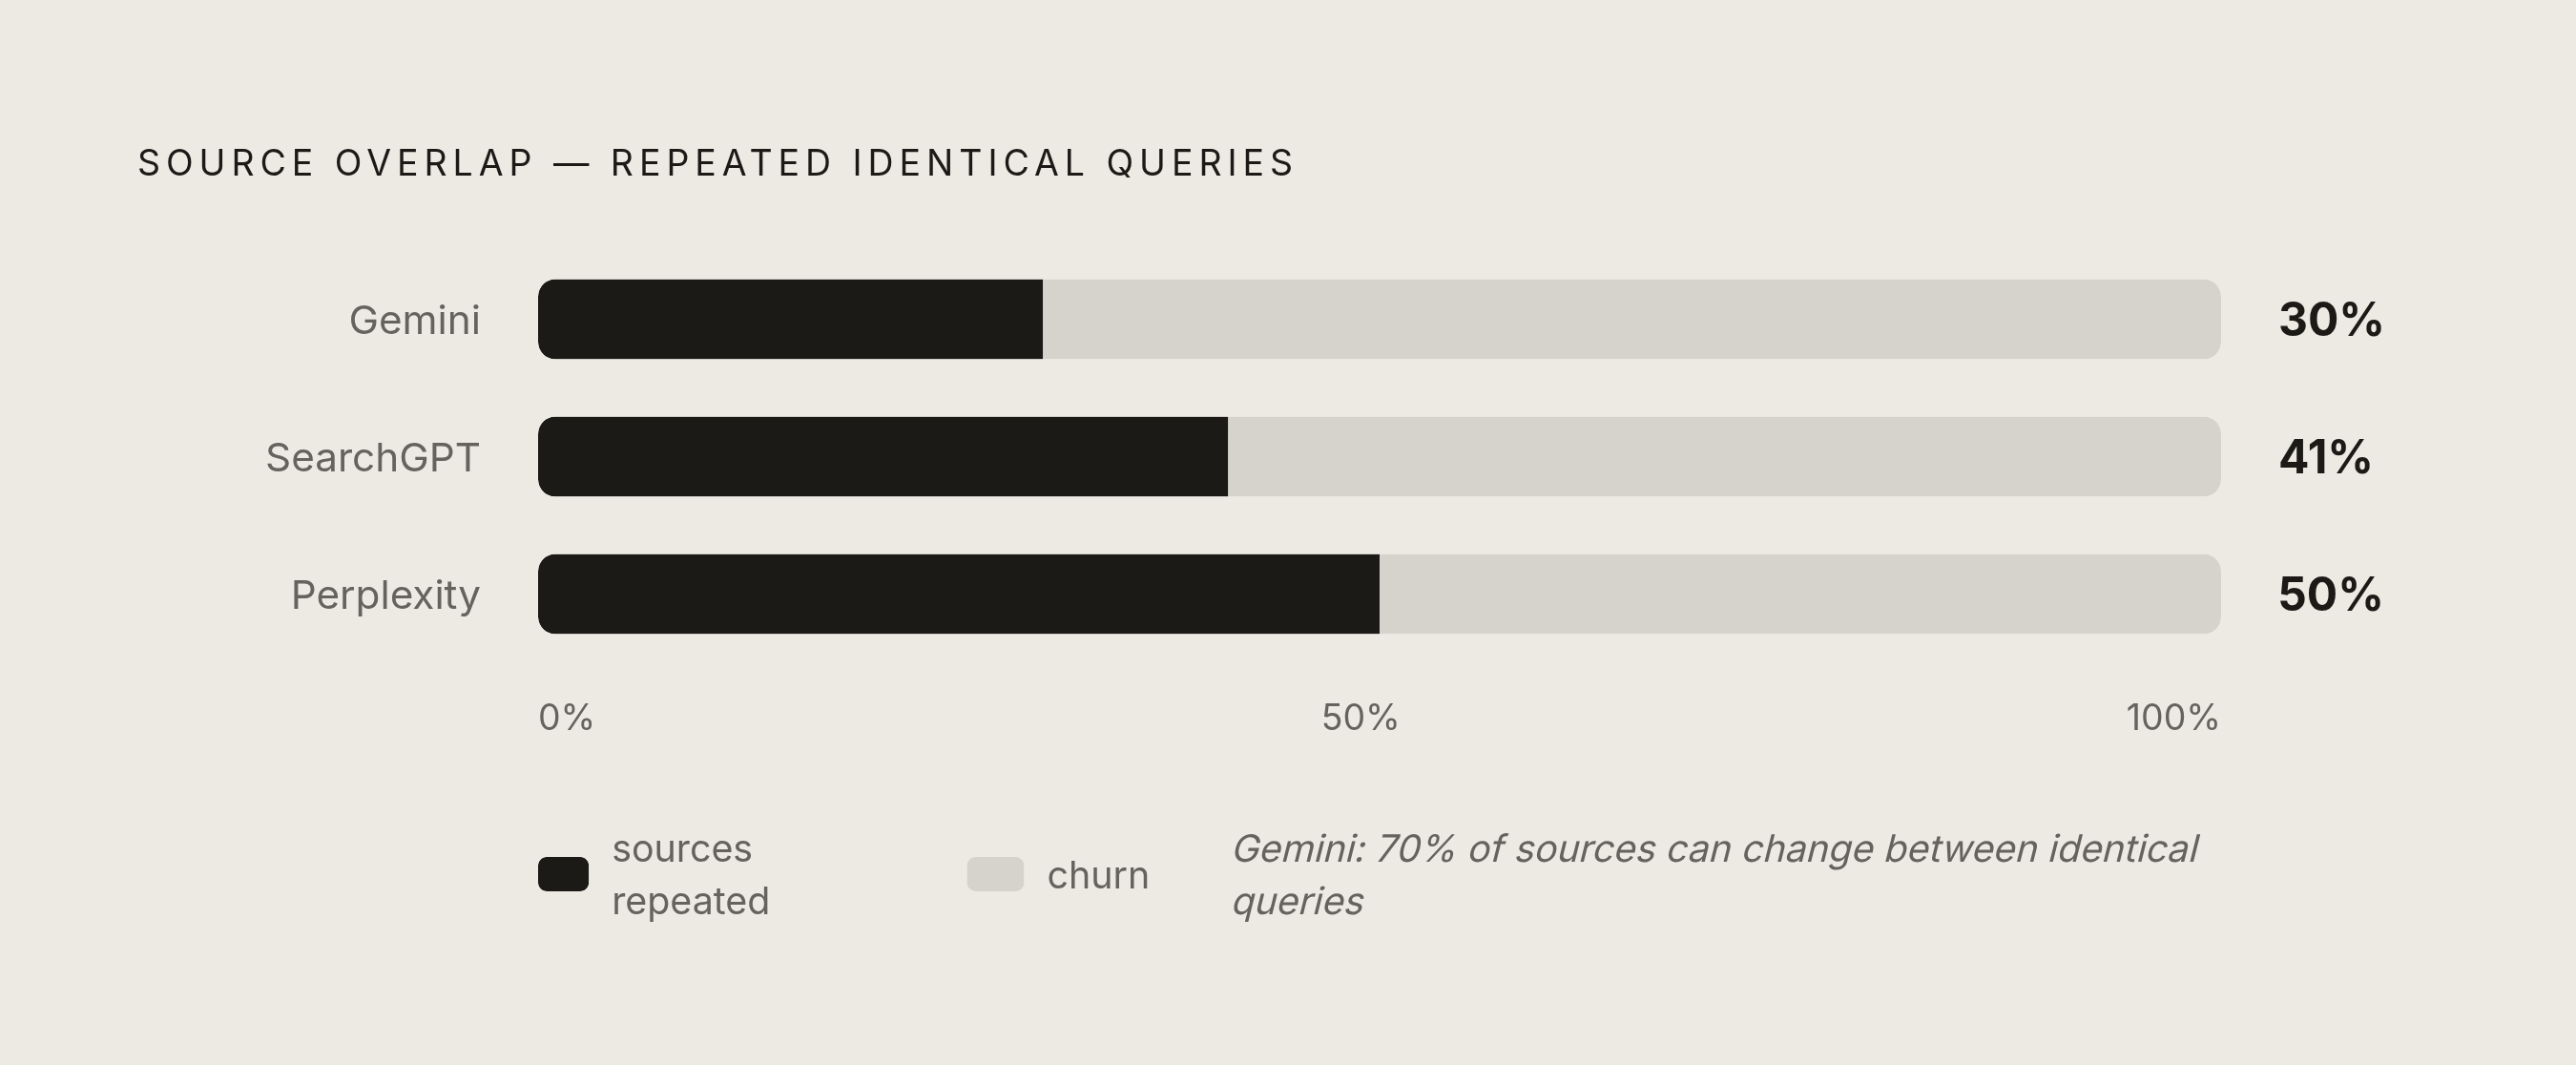
Research backs this up directly. A paper out of the University of St. Gallen, titled "Don't Measure Once" (Schulte et al.), argues that GEO performance has to be treated as a distribution rather than a single data point, precisely because the probabilistic nature of AI search makes any one-off observation unreliable. Separate analysis from Forbes (Goldberg) measured how much the underlying sources overlap when the identical query is run repeatedly on the same platform, and found roughly 30% overlap on Gemini, somewhat higher on SearchGPT, and around half on Perplexity. The instability is worst on exactly the queries that matter most commercially, the ones carrying real purchase intent, where a buyer is comparing options and a brand's presence or absence actually affects a sale.
The consequence for anyone reading a dashboard is direct. If a tracking report shows citation share climbing from one period to the next, say from 8% to 11%, that movement can sit entirely inside the ordinary noise of how these engines regenerate answers, with no real change in the brand's underlying visibility at all. None of this stems from sloppy vendor work. It is a property of the engine itself, and it holds true no matter which tracking tool a marketer chooses to use. The measurement layer built on top of these engines deserves its own separate scrutiny.
Why the tools measuring AI visibility compound that instability rather than correct for it
The instability built into the engines gets worse, not better, once GEO platforms start collecting and reporting on it. Three problems in how these tools gather their data pile on top of the engine's own unpredictability.
The first is the prompt set itself. Every major GEO platform tests brand visibility against a library of "queries a buyer might ask" that the vendor writes and curates in-house, not the actual stream of questions real users type into ChatGPT, Claude, or Gemini, a stream no outside platform can access. The panels used to build these synthetic prompt sets are often opt-in, and opt-in panels carry a documented bias problem of their own: they produce error rates that run several times higher than panels built from proper probability sampling.
The second problem concerns where the data comes from technically. Tracking platforms typically query a developer API to generate their results, while the customer interacts with a consumer app that carries memory of past conversations, personalization, location signals, and model-routing logic that the bare API call never triggers. The product being scored is not the product the buyer actually uses.
The third problem is that the tracked prompt often is not the prompt the engine ever ran. Modern AI assistants break a single question into sub-queries and run them in parallel, a process Google calls query fan-out, and the company says its Deep Search feature can issue hundreds of these sub-queries just to answer one complex question. A dashboard that tracks one static phrase is grading a test the engine never actually took.
Three problems in how these tools gather data combine with a sampling problem. You need 40–50 queries per topic on one platform, and 150 or more on another, to reach a defensible estimate of visibility, but most brand dashboards run a small handful of prompts each week and still report the result to one decimal place. A 2026 ranking of nine AI optimization platforms found that eight of the nine never publish their dataset size at all, so you can almost never check the sample depth behind a vendor's headline number. An inadequate sample is a technical shortfall, conveniently invisible to the customer paying for the report.
The vendor conflict of interest built into the measurement-and-optimization model
The sampling issue causes a deeper problem: a conflict of interest built into who produces the score. When the company selling AI visibility optimization is the same company producing the score that proves the optimization worked, the structure itself rules out independent verification, regardless of whether the vendor is acting in bad faith.
Metricus, a competing GEO tool vendor, laid out the core problem in April 2026: no major GEO platform publishes the methodology behind its AI visibility score. The formula is kept proprietary, the prompt set stays undisclosed, and the entity reporting the result is the same entity whose product that result is supposed to evaluate. An independent review of the methodology behind one leading platform's data turned up six structural flaws, among them a severely limited data source, a skewed user panel, and extrapolation errors that get amplified as the data moves through the pipeline. Commentators have called scores built this way vanity metrics with undisclosed weights: the number on the dashboard goes up, and the buyer has no way to tell whether that increase reflects a real gain in visibility, a quiet refresh of the prompt set, or a recalibration of the formula itself.
There's a useful historical comparison here. Audience measurement in broadcast television faced the same credibility problem, and one long-established ratings provider, the closest real analog to today's GEO prompt panels, took decades of refinement, public auditing by an independent industry oversight body, and annual third-party validation before the broadcast industry trusted its numbers. Nielsen still lost its MRC accreditation for 19 months after it was found to have undercounted TV household viewers, including an undercount of adults 18 to 49 by as much as 6%, during the pandemic. Digital advertising ran into a version of the same issue when Facebook's video viewing metrics were found to be inflated for over 18 months before the company disclosed it, and what resolved that crisis was not a better proprietary score but structural independence: the measurement function was separated from the entity whose performance it was measuring.
That history points to the one question that actually matters when evaluating a GEO vendor: can the methodology, the prompt set, and the underlying model calls be inspected by someone outside the company, or is the vendor grading its own homework? Framing the issue this way is a structural condition that applies to the category as a whole, not an accusation against any particular company, and marketers who understand it know which audit questions to ask before they sign a contract.
Hallucinations and Citation Post-Rationalization in Visibility Scores
A visibility score can be built with a sound methodology and still track something worthless, because the AI answers it counts may describe the brand inaccurately. High visibility and brand misrepresentation can coexist, and one can even cause the other.
Hallucination rates across major models have dropped a lot since the early days of these systems, but accuracy still swings widely depending on how you test it. One model's accuracy dropped from strong performance under controlled conditions to well below half once the evaluation conditions changed, and another model's accuracy fell from above 90% to a small fraction of that under different test conditions. A concrete example from 2026 shows what that looks like in practice: Cursor's AI support bot told users they were restricted to "one device per subscription," a policy the company had never actually set, and the false claim led users to cancel subscriptions and request refunds before Cursor acknowledged the statement was a hallucination. That incident was not a strange exception. It represents the standard level of risk facing any brand that AI systems discuss with apparent confidence but without a guarantee of accuracy.
Citations compound the problem rather than solving it, because many of these systems generate an answer first and attach supporting links to it afterward. Researchers call this post-rationalization: the citation looks plausible sitting next to the claim, but it was not actually what produced the claim in the first place. For a visibility score, the implication is direct. A brand mentioned often is not the same as a brand described accurately, so a score that counts mentions without checking what they say is measuring noise and calling it signal.
How platform divergence makes cross-platform scores meaningless
The differences in how ChatGPT, Perplexity, Gemini, and other engines source and cite brands run wide enough that averaging all of them into one visibility score hides the exact variation a marketer most needs to see.
AEO & GEO Statistics for 2026, published by Instant Press, documents how differently these platforms actually source their answers. ChatGPT's top-cited source is Reddit, a pattern that reflects the encyclopedic depth of its training data rather than a live search of the web. Perplexity also cites Reddit heavily, but for a different reason: it emphasizes real-time community content and recency. Perplexity is also one of the more trackable major AI platforms inside GA4, since it consistently includes clickable inline citations, and ChatGPT has passed trackable referral data through utm_source=chatgpt.com since mid-2025. Two platforms citing the same source for entirely different structural reasons is the variation a brand actually needs to see broken out by engine, not a detail to collapse into one aggregate number.
LLMrefs' GEO audit framework found that in 82.5% of AI search audits, the brand that would have answered a query best was either missing from the answer or buried inside another cited source. Aggregating results across platforms into a single score hides which specific engine is actually serving a brand's target audience, since the engine doing the best job for that brand can get washed out in an average with engines doing a worse job. Some platform pricing structures make the problem harder to catch, not easier. A 2026 ranking of platforms found that some vendors gate engine coverage by price tier: customers on lower-priced plans see a ChatGPT-only score, while multi-engine tracking is reserved for higher tiers, so marketers on standard plans look at an incomplete picture presented to them as if it were complete. Platform-level visibility scores, broken out one engine at a time, are the smallest useful unit of measurement here. An aggregate score that flattens the differences between engines does not summarize the data. It suppresses the exact signal a marketer would need to act on it.
Minimum viable measurement practice
Treating AI visibility as a distribution rather than a single point estimate changes what a responsible measurement practice has to look like, not by throwing out scores altogether, but by building the surrounding infrastructure needed to make sense of them. The tools measuring AI visibility often compound that instability instead of correcting for it, because they inherit the same volatility while they present it as a stable score.
Prompt set design matters as much as how often a brand runs its tracking. A responsible prompt set needs buyer-stage prompts, direct comparison prompts, problem-aware prompts phrased the way a frustrated customer would actually phrase them, and both branded and unbranded versions of each, because visibility shifts with the wording and intent behind a question, not only with which engine answers it. If a prompt set is built only around awareness-stage questions, it will miss the purchase-intent gap entirely, and that stage is exactly where the instability documented earlier runs highest.
MaxAEO's AEO software framework proposes a model it calls the Evidence-to-Answer Loop as a better way to diagnose exactly which stage of AI visibility is breaking down: crawl access, retrievable evidence, trusted source selection, answer synthesis, recommendation placement, and conversion path. A tool that cannot identify which stage of that loop is broken for a given brand will hand back a report with no real action attached to it, regardless of how precise the headline number looks. A single dashboard score cannot tell a marketer whether a brand is failing because crawlers cannot reach its content, because its content exists but isn't trusted as a source, or because the synthesis step is choosing a competitor instead.
The more defensible practice breaks the score apart rather than trusting it whole: share of voice measured separately by engine, the type of source behind each citation, and a direct check of brand accuracy in what gets said. None of those three pieces fits neatly on one dashboard tile, and that is the point. A single number was always too small a container for what is actually a moving, probabilistic, multi-engine system, and the marketers who get real value out of AI visibility tracking are the ones willing to look at the pieces instead of the summary.