Procurement Timeline and Switching Costs for AEO Platforms
Buying an AEO platform requires aligning content, PR, and technical work for months to see results.
Buying an answer engine optimization platform is not like buying a CRM or an email tool, because the product's value depends on work that happens mostly outside the platform itself: content quality, off-site authority, coverage across multiple AI engines, and results that take months to show up. A CRM works the day it's configured. An AEO platform only works if the content team, the PR function, and the technical SEO stack all move in the same direction after the contract is signed.
The stakes of getting this wrong are sharper than they look. AI-generated answers draw from a small set of sources, typically three to ten depending on the engine and the query, which makes the citation pool far more concentrated than a page of ten blue links ever was. Citation frequency is a spectrum, not a hard cutoff, so pages outside the traditional top 100 organic results can still pick up AI-referred traffic. But a brand that never appears in that small citation set is functionally invisible to a buyer who reads the AI answer and never scrolls further. There is no page two to fall back on. A wrong or delayed platform decision does not just cause a dip in performance, because it means zero presence during the exact window when a competitor earns citations that compound.
Compounding that risk is the fact that nobody buying into this category has done it before. The market was barely formed before 2024 and accelerated sharply through 2025 and 2026, so procurement teams are evaluating vendors without the years of comparison shopping and shared vocabulary that make buying an SEO platform or a CRM comparatively routine. That combination, concentrated stakes and no institutional memory, means the procurement decisions ahead need examining stage by stage rather than assuming the category behaves like any other software line item.
The three-tier market structure
The AEO and GEO market has settled into three distinct products sold under the same label, and a team that shops the wrong tier ends up negotiating rate inside a product that cannot deliver what it needs. At the entry level sit self-serve monitoring tools, priced according to how many engines they track and how many prompts a team runs through them each month. These tools answer a narrow question: where does a brand stand across ChatGPT, Perplexity, Gemini, and the rest, on a defined set of queries, measured on a regular cycle.
The middle tier is made up of agency retainers, where pricing shifts based on the scope of work and the number of engines covered. These retainers typically bundle monitoring with active work: content rewrites, schema markup, digital PR outreach aimed at the kind of third-party citations that AI engines draw from. Highly regulated categories, fintech, healthcare, legal, and insurance, carry a price premium over comparable work in less regulated industries, because compliance review, sourcing standards, and authority requirements add real labor on top of the baseline scope.
The danger across all three tiers is the same: funding measurement without funding the work that measurement is supposed to inform. A mid-market team can spend a meaningful amount every month on a monitoring subscription and watch citation share stay flat because no budget exists for the content production, schema deployment, or outreach that would actually change what the AI answer says. Monitoring tells a team where it stands. It does nothing, by itself, to move that position. Before any procurement conversation goes further, the question a buyer needs answered is not "which vendor" but "which tier," because a mismatch between tier and budget is the single most common reason an AEO engagement stalls in its first two quarters.
The procurement timeline
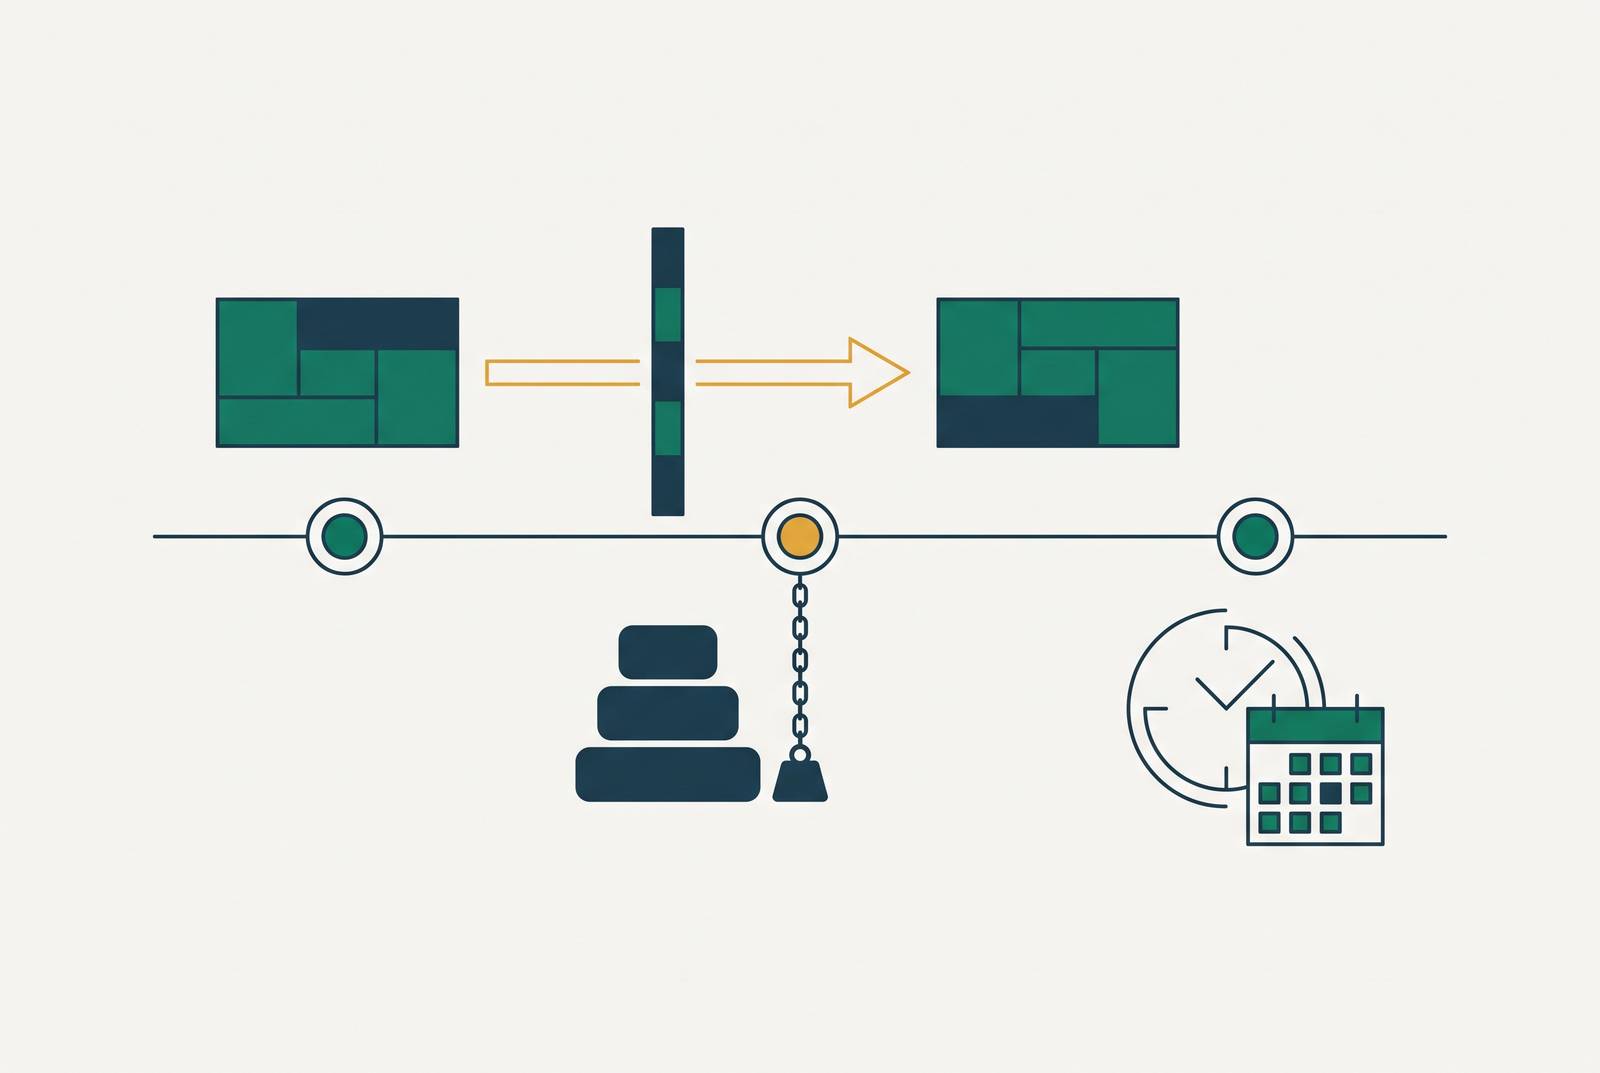
Most marketing teams underestimate how far it is from recognizing they have an AI visibility problem to having a program that actually produces citations. That gap breaks into four stages, and each one carries its own built-in delay.
The first stage is diagnosis, and it typically starts with a demonstration: someone shows the gap on screen before anyone writes a strategy memo. The most effective version of this, documented across the category, is simple: someone asks "do you know what ChatGPT says about your brand?" and then shows the answer on screen in real time. When a marketing leader sees competitors named in the response and their own brand missing from it, the conversation shifts immediately from whether this matters to how quickly a program can start. That emotional jolt is useful for building urgency, but it can also compress the evaluation phase to the point where teams sign with the first vendor who ran the demo, rather than the vendor best suited to their tier and budget.
The second stage is internal alignment, and it tends to run longer than teams expect because AEO sits awkwardly between departments. It touches marketing, content, SEO, sometimes IT, sometimes legal, and none of those functions has owned anything like it before. Because the category didn't exist as a budget line two or three years ago, there is rarely a pre-approved allocation waiting for it. Someone has to build the business case from the ground up, even when the executive sponsor is already convinced. The strongest internal argument tends to be the binary framing itself: a brand is either part of the small set of sources an AI answer cites, or it isn't, with no partial-credit middle ground to point to in a budget memo.
The third stage is vendor evaluation, and this is where credible providers separate from rebranded SEO shops. A useful first question is whether a vendor can name the specific engines they track, ChatGPT, Perplexity, Google AI Overviews, Claude, Copilot, and show evidence of coverage across each, rather than selling "AI SEO" as a vague, undifferentiated bundle. Coverage across engines is not a formality. Test the same brand against the same set of queries, and you can see meaningfully different citation share on Perplexity versus ChatGPT versus Gemini versus Claude, so a tool that only covers one engine can hand a team a false sense of completeness. You should also ask whether the platform stops at monitoring or closes the loop: it should surface specific content gaps, recommend schema fixes, and help produce the kind of content AI engines are more likely to cite. A third is simpler and often overlooked: is pricing published, or is everything hidden behind a discovery call? Vendors that won't put a number on a page make it hard to model a budget in advance, and that opacity often signals room for the number to move upward once a prospect is already emotionally committed from stage one.
The fourth stage is pilot definition. For any engagement of real size, this is where a buyer has the most leverage. Before signing a twelve-month commitment, a defined pilot window with citation KPIs tied to specific engines should be a non-negotiable term in the contract, not a verbal promise. The trouble is that pilot windows run into the structural lag built into how AI visibility actually changes, and that lag needs understanding on its own before any contract gets signed.
Why results lag and create lock-in before switching costs
AI visibility does not move on a content calendar. It moves when model weights get updated, when grounding indexes refresh, and when competitors' own content and citations shift, all on timetables set by the model providers. A piece of content optimized this week might not show measurable citation lift for months because the underlying index it depends on hasn't refreshed yet.
Attribution makes the lag harder to see. High-intent B2B buyers increasingly use large language models to research vendors before they ever visit a website, but an AI answer synthesizes information without requiring a click, so the buyer who eventually does visit often arrives by typing the URL directly or searching the brand name. Standard analytics logs that visit as direct traffic with no prior touchpoint, erasing the AI research step from the record. A program can be influencing real buying decisions even when every dashboard a marketing team looks at shows nothing connecting the two.
That combination, slow-moving citation data and an attribution trail that hides its own effect, creates real pressure to switch vendors during exactly the window when switching is least justified. A team three or four months into a program, watching flat citation numbers and seeing no AI-sourced traffic in its analytics, has every reason to conclude the program isn't working, even when it is. The answer to that pressure is a better measurement setup, layering visibility signals like prompt-set share of voice and citation frequency with demand signals like branded search lift and direct traffic to pricing pages, and revenue signals like AI-attributed pipeline where it can be tracked, to give a team a clearer read on progress before the lagged citation data catches up. If teams build this layered view before they sign, they can judge their own program honestly instead of mistaking measurement lag for program failure.
The real switching costs: what a team loses when it changes AEO platforms or vendors
The costs of switching AEO vendors are mostly invisible at the moment a contract is signed, and understanding them in advance is the strongest argument for getting the first vendor decision right.
The first cost is data portability. AI-visibility data, the prompt sets tested, the citation frequency tracked over time, the share-of-voice trend lines, is not standardized across platforms. Switching vendors usually means starting the data-accumulation clock over from zero. Historical citation data is the one way to tell whether a program is working slowly or not working. Losing that history mid-engagement doesn't just cost time, it removes the one tool a team has for making that judgment correctly.
The second cost is workflow. The most durable form of lock-in in this category isn't contractual, it's operational: schema templates, content briefs, prompt libraries, and citation-monitoring dashboards get built inside one platform's interface and don't transfer cleanly to a replacement. A content team that has restructured its production process around one platform's gap recommendations faces more than a data migration when it switches. It faces rebuilding the process itself.
The third cost is contractual, and it's specific to the agency tier. Retainers with six- to twelve-month minimums mean a team that decides to leave after month three is still paying for months four through six, or four through twelve, while simultaneously paying a new vendor to onboard. That's a period of double-spending at exactly the moment a team expected to start saving money by making a change. Hybrid retainer models that include performance bonuses add a further complication at the point of termination: verifying whether a citation gain came from the agency's work or from a natural refresh of the underlying LLM corpus requires detailed telemetry that most teams simply don't have on hand when the contract ends, which can turn an exit into a dispute over what's actually owed.
SaaS monitoring platforms and agencies carry an asymmetry in how switching costs hit each one. SaaS monitoring platforms are usually month-to-month or carry short commitments, so switching tools is lower-friction on the contractual side, but it still resets the baseline data clock. Agency switching carries harder contractual and financial friction on top of the same workflow and knowledge costs. That asymmetry points toward a sequencing strategy: establish platform-level measurement first, let baseline data accumulate, and only then select an agency based on what that data actually shows, rather than buying a platform and an agency on the same timeline and hoping they turn out to fit.
Not everything is lost in a switch. Content produced during an engagement generally stays usable afterward, and earned citations or digital PR placements don't disappear when a vendor relationship ends. The off-site authority a program builds is durable in a way the platform relationship itself is not, which is a reasonable argument for treating content and PR investment as worthwhile even for a team still deciding on its long-term vendor setup.
The agency-versus-platform decision
For most mid-market teams, framing this as a choice between a platform and an agency misses how the two actually function. They do different jobs, and the hybrid setup that shows up repeatedly in practice follows naturally from how citation share actually moves.
A platform does something an agency, run manually, cannot match: continuous, daily monitoring across multiple models at machine cost, running hundreds of prompt sweeps, flagging citation gaps, and tracking share of voice across engines without waiting on a person's schedule. The manual alternative, someone logging into AI tools, typing out queries by hand, capturing the responses, and assembling a slide deck, introduces delay at every step and bills for hours worked. Platforms built for this reality treat AEO procurement as a way to track visibility and citation presence across eight or more major language models at once, because the category's value depends on factors no single dashboard can show. Enterprise-grade platforms go a step further by closing the loop between watching and acting, pairing cross-model citation testing with content gap identification and schema recommendations inside one command center, so that money spent on the platform is tied directly to the work that changes the citation outcome.
An agency does something a platform cannot do on its own: rewrite the actual content, build and deploy schema markup, run digital PR campaigns, and land the third-party citations that AI engines draw on as source material. Software can show a brand exactly where it stands relative to competitors across every tracked engine. It cannot, by itself, fix the content gaps or the missing authority signals that explain why the standing looks the way it does. When evaluating a vendor at the Stage 3 point in procurement, the central question is whether it can demonstrate coverage across the specific engines that matter, ChatGPT, Perplexity, Claude, Copilot, and others, rather than selling an undifferentiated "AI SEO" package. If a tool doesn't track eight or more models, it isn't a genuine AEO platform, just a traditional SEO tool repackaged with new branding.
The pattern that emerges for most mid-market teams running both pieces well looks consistent: a platform runs year-round for daily measurement and alerting, while a scoped agency engagement, a content overhaul, a PR sprint, a technical schema restructure, gets brought in for a defined project and then released back to platform-only monitoring once that work is done. That structure avoids paying ongoing retainer rates for work that happens in bursts rather than continuously, and the baseline measurement keeps running underneath it, producing the data that makes a future platform switch costly and a future agency decision evidence-based rather than a guess.